⚡ AI News
Anthropic: AI agents now outnumber staff six to one: Anthropic's internal report says Claude agent hours topped employee hours sixfold by August, with hiring shifting away from junior roles.
Replit CEO says it dropped Anthropic for OpenAI: Replit's CEO says the coding platform now defaults to OpenAI over Claude on cost and quality, though insiders dispute the switch.
Meta walks back AI scraping language in site terms: Meta reversed new commercial terms that would have let it scrape publisher sites for AI training after a legal backlash.
👍1
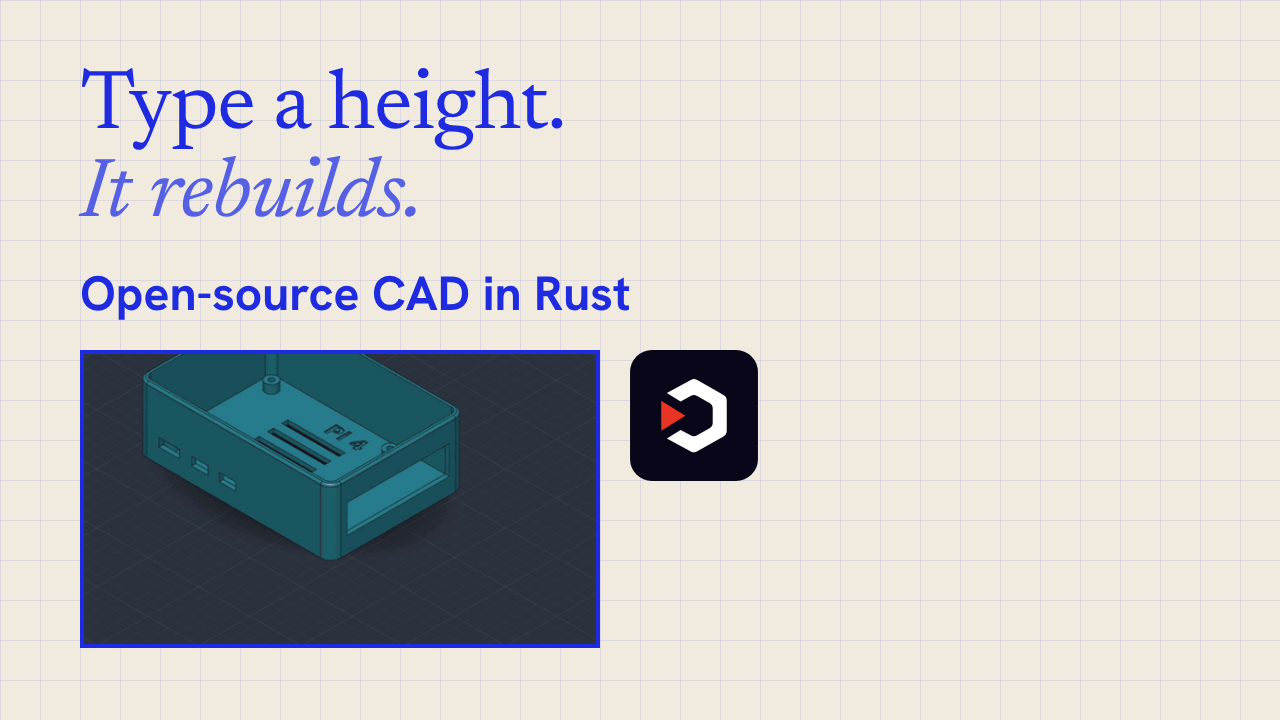
Change one number, and the whole model rebuilds
Typed a new height, 24 to 32 millimeters, and this whole case updated itself.
That's SolidCraft, an open-source parametric 3D CAD built in pure Rust.
▶️ Watch the video on YouTube
Live rebuild: edit a dimension, the model regenerates automatically
Feature timeline: every sketch and fillet stays editable, not baked in
Desktop or browser: the same CAD runs natively, or opens with no install
MCP server: AI agents can sketch, extrude and fillet through it too
Not signed yet: Windows SmartScreen and macOS Gatekeeper will warn you
tangency-labs/solidcraft
Typed a new height, 24 to 32 millimeters, and this whole case updated itself.
That's SolidCraft, an open-source parametric 3D CAD built in pure Rust.
▶️ Watch the video on YouTube
Live rebuild: edit a dimension, the model regenerates automatically
Feature timeline: every sketch and fillet stays editable, not baked in
Desktop or browser: the same CAD runs natively, or opens with no install
MCP server: AI agents can sketch, extrude and fillet through it too
Not signed yet: Windows SmartScreen and macOS Gatekeeper will warn you
How the rebuild works, and what it needs
Every sketch, extrude, fillet and shell lands on a parametric feature timeline. Edit one dimension (the demo changes a case height from 24 to 32 mm) and SolidCraft reruns the timeline from that step onward, so the whole model regenerates instead of breaking.
The app runs natively on Windows (x64, ARM64 and x86), macOS (Apple Silicon and Intel) and Linux (AppImage, .deb, .rpm, Flatpak, Snap), or straight in the browser with no install at all. A built-in MCP server lets external AI agents sketch and extrude through SolidCraft too. The agent you connect still needs its own API key or local model: SolidCraft doesn't supply that intelligence.
Requires: Windows, macOS or Linux for the native app, or just a browser for the web build. The README lists no GPU or memory requirement.
The catch: builds aren't code-signed yet. On Windows, SmartScreen will warn you, choose More info, then Run anyway; on macOS, right-click the app once and choose Open.
SolidCraft itself is free and open source under its licence. Install withwinget install bherbruck.SolidCrafton Windows,sudo snap install solidcrafton Linux, or grab the DMG or AppImage from the Releases page, or just try it at solidcraft.io/app with nothing to install.
Use it instead of Fusion 360 or SolidWorks when you want a free, self-hostable parametric CAD you can script. Don't reach for it yet if your workplace needs signed installers before it will even run an app.
tangency-labs/solidcraft
😁1
⚡ AI News
Anthropic: Claude use cut junior hiring from 27% to 9%: Anthropic says junior technical hires fell from 27% to 9% since early 2025 as meeting time rose 20% per employee.
Legal experts: Meta's new terms still allow news scraping: Despite Meta's walk-back this week, three legal experts say its Oct 30 commercial terms still let it scrape news sites for AI training.
Disney to hire 60+ Character.AI staff after bankruptcy: Court filings show Disney is paying about $60M a year to hire the majority of Character.AI's workforce following its Chapter 11 bid.
🏆1
Your AI coding agent never has to forget again
A coding agent eventually runs out of context and loses the thread. billion-context sits between the agent and the model as a proxy, rewriting the conversation on the fly so that never has to happen.
▶️ Watch the video on YouTube
Proxy in the middle: rewrites the request and response stream live
Reversible compression: the model itself folds old turns into layered summaries
Cache stays warm: the prefix barely changes, so prefix caching still works
Months on one chat: a 100K-token model can now run for weeks without restarting
Big claims, young repo: its own study reports billions of tokens moved, zero violations, in ten weeks
How it actually works
billion-context runs as a local proxy (CLI commandbili) sitting between your agent and the model's API, in Anthropic or OpenAI format. It injects four tools the model can call on itself:compress,decompress,search_contextandacp_status, folding older turns into layered, reversible summaries instead of a hard context cutoff or a blunt auto-truncate.
Two ways to run it: a launcher that spawns agent and proxy together (bili pi,bili codex, and so on), or a URL-prefix proxy mode (http://localhost:8787/bili/...) for any client that lets you set a base URL. The project lists Claude Code, Codex, Cursor, Aider, OpenCode, Zed and 20+ other agents as supported.
The numbers come from the project's own production study, not an outside benchmark: 4.5 months across three hosts, 174,327 model calls, 18.76 billion cumulative input tokens, zero context-window violations on 204,800-token models, compression overhead under 2% of the token budget, and a 95 to 97% prefix-cache hit rate on healthy sessions.
billion-context itself is free and open source. It doesn't run a model: you connect your own API key, so whoever hosts that model is what you still pay for.
Requires: Node.js and npm, a model API key, and an agent or client that supports a custom base URL or one of the built-in launchers.
The catch: the repository was only created about ten weeks ago, despite already claiming that months-long dataset and nearly 1,900 stars, so nobody independent has verified the numbers yet. The MIT license also carries an attribution clause: ship it in a product, and you must link back to the repo.
Use it instead of paying for a model with a huge native context window when a cheaper, smaller model is good enough otherwise. Don't use it if your agent isn't on the supported list or you need something with an independent track record.
Try it withnpm install -g billion-context, then runbili pi(orbili codex, etc.) to launch the agent and proxy together.
❤1🔥1
👏2
⚡ AI News
Anthropic pledges 5% of shares to benefit fund: Anthropic will commit 5% of its equity, rising toward 20% with co-founder pledges, to a new public benefit fund.
DeepMind agents beat Minecraft solo in 27 hours: Four Gemini 4 Argon agents defeated Minecraft's Ender Dragon from a random spawn with no human help, in 27 hours.
Sam Altman's World launches ID suite for banks: World's new ID suite lets banks flag deepfake callers, as AI fraud losses are projected to hit $40B by 2027.
💯1
Your coding agent reads too much. Headroom cuts it down before the model ever sees it.
Logs, tool output, RAG chunks, whole files: all of it hits your agent's context raw.
Headroom compresses it on your machine first, same answers, way fewer tokens.
▶️ Watch the video on YouTube
Compress everything: tool outputs, logs, RAG chunks, even whole files
10,144 to 1,260 tokens: Headroom's own demo, the FATAL log line survives byte for byte
Three ways to run it: a Python/TS library, a local proxy, or an MCP server
One command, any agent:
55,957 to 24,340 tokens: the README's own example, the critical line stays intact
headroomlabs-ai/headroom
Logs, tool output, RAG chunks, whole files: all of it hits your agent's context raw.
Headroom compresses it on your machine first, same answers, way fewer tokens.
▶️ Watch the video on YouTube
Compress everything: tool outputs, logs, RAG chunks, even whole files
10,144 to 1,260 tokens: Headroom's own demo, the FATAL log line survives byte for byte
Three ways to run it: a Python/TS library, a local proxy, or an MCP server
One command, any agent:
headroom wrap claude covers Claude Code, Cursor, Codex and more55,957 to 24,340 tokens: the README's own example, the critical line stays intact
How Headroom compresses context, and what it costs
A ContentRouter looks at what's coming in and picks a compressor: SmartCrusher for JSON, an AST-based CodeCompressor for source code, and a small HuggingFace model (Kompress-v2-base) for plain text. A CacheAligner flags volatile content that would bust a provider's KV-cache prefix, without rewriting anything. What gets stripped stays cached locally (CCR), so the model can callheadroom_retrieveand pull the full original back if it needs it.
The numbers are the project's own. The demo GIF shows a 10,144 token log dump shrinking to 1,260 while the FATAL line survives; the README's hero example shows 55,957 tokens of agent prompt becoming 24,340 sent, with the critical line intact at item 67. The README also ships a seeded, offline benchmark script,benchmarks/index_proof_table.py, so these figures can be reproduced rather than just taken on faith.
Requires: Python 3.13 for the full CLI, viauv tool install --python 3.13 "headroom-ai[all]"orpip install "headroom-ai[all]". The npm packageheadroom-aiis a TypeScript library only, no CLI included. Whatever LLM you point it at, Anthropic, OpenAI, Bedrock and so on, still needs its own paid API key: Headroom only shrinks what you send, it doesn't make the model itself free. The project doesn't list GPU or hardware requirements for running the bundled text model locally.
The catch:headroom wrap claudealso installs Serena for semantic code navigation alongside it, scoped to that project unless you pass--code-memory-scope useror skip it with--code-memory none.
Use it instead of piping raw logs or JSON tool results straight into Claude Code or Cursor when your agent keeps choking on context. Don't reach for it if you want one zero-setup command: wrapping brings Serena along too.
Try it:headroom doctorchecks routing,headroom dashboardshows live savings once the proxy is running. Apache 2.0 licensed.
headroomlabs-ai/headroom
🥰1
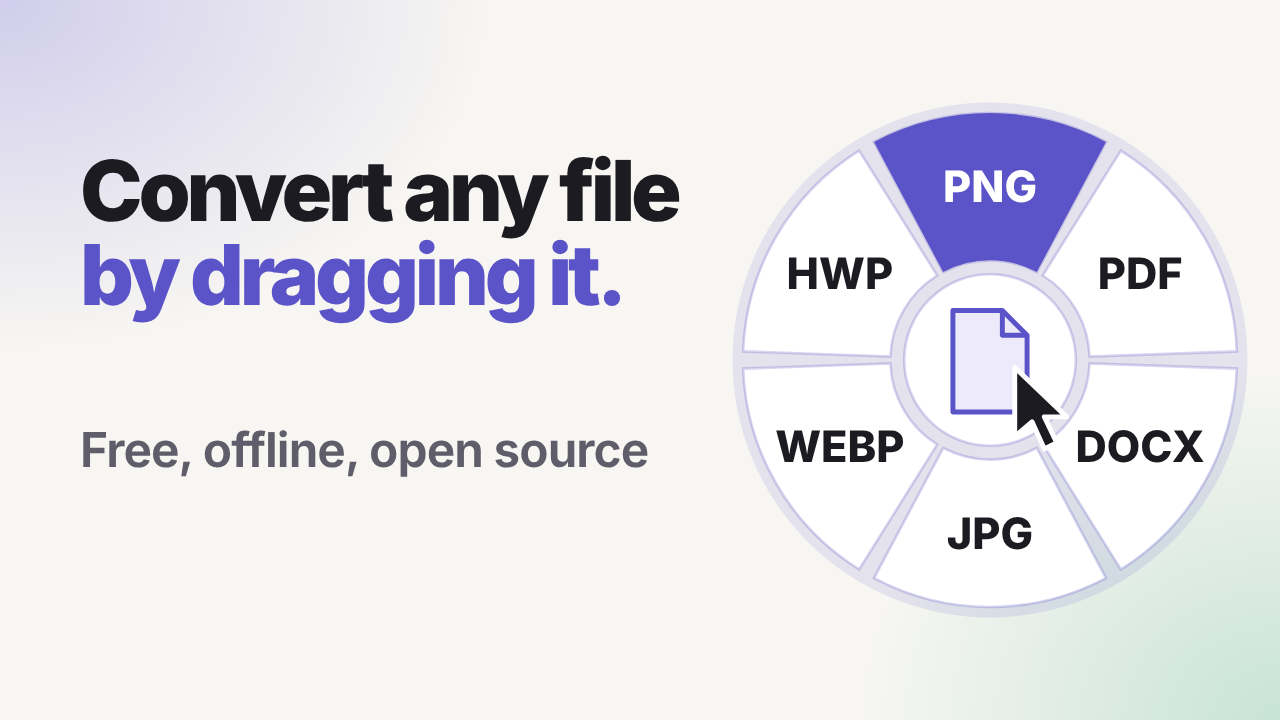
Drag a file onto a donut, get it converted on the spot
Filee is a free, open-source converter you use by holding Ctrl and dropping a file on a format in a wheel that opens right at your cursor. No app window, no upload.
▶️ Watch the video on YouTube
Drag, don't open: hold Ctrl, drop files on a format in the donut that opens at your cursor
244+ formats, offline: images, PDF, Word, Excel, PowerPoint, HWP/HWPX, video, audio, e-books, archives
No Office needed: DOCX, XLSX, HWP convert without Office, Hancom Office or LibreOffice installed
Batch and smart routes: converts many files at once, and finds routes itself like HWP to HWPX to DOCX
Mac and Linux still in preview: Windows 10/11 is the stable platform today
github.com/KnifeLemon/Filee
Filee is a free, open-source converter you use by holding Ctrl and dropping a file on a format in a wheel that opens right at your cursor. No app window, no upload.
▶️ Watch the video on YouTube
Drag, don't open: hold Ctrl, drop files on a format in the donut that opens at your cursor
244+ formats, offline: images, PDF, Word, Excel, PowerPoint, HWP/HWPX, video, audio, e-books, archives
No Office needed: DOCX, XLSX, HWP convert without Office, Hancom Office or LibreOffice installed
Batch and smart routes: converts many files at once, and finds routes itself like HWP to HWPX to DOCX
Mac and Linux still in preview: Windows 10/11 is the stable platform today
What Filee needs, and what still doesn't work everywhere
Filee runs every conversion on your own machine. There is no account and no API key involved, nothing calls a cloud model, so "free" here means no cost: it's the project's own build and your CPU doing the work, nothing to pay for.
The project's own README lists 246 formats working with no other software installed; the description used for this video rounds it to 244+. Either way, most of it (images, PDF, DOCX, XLSX, PPTX, HWP/HWPX, text, e-books, archives, fonts, data, 3D models) needs nothing extra. A smaller set (older vector formats, legacy office docs, markup conversions, video and audio) pulls in an optional engine, Ghostscript, LibreOffice, Pandoc, calibre or FFmpeg, downloaded only the first time it's needed. Separately, Trendshift ranked it the week's #1 C# repository, which is an independent signal, not a benchmark.
Requires: Windows 10 or 11 for the stable build. macOS 14+ and Linux x64/ARM64 (Ubuntu 22.04+) builds exist but the project itself marks them preview; macOS isn't notarized yet, so the first launch needs Open Anyway in Privacy & Security; Linux needs Python 3, no root, and X11 for drag gestures (Wayland users get the drop zone and right-click menu instead).
The catch: anywhere outside Windows, you're on a preview build, and the project says so itself rather than hiding it.
Grab it from Releases, or once installed run it from a terminal:filee convert photo.heic --to jpg. Use it instead of opening Word, Acrobat or an online converter when a file just needs to change format without leaving your machine. Don't reach for it yet if you specifically need a solid macOS or Linux build: those are still preview.
github.com/KnifeLemon/Filee
😁1
⚡ AI News
Hackers breach OpenCode, drain users' AI credits: A breach of OpenCode's console leaked API keys and caused unauthorized charges on OpenAI, Anthropic and Google accounts.
Nvidia launches Nemotron 3.5 open models for agents: Nvidia's new Nemotron 3.5 models run AI agents on PCs and in enterprises, claiming speed gains over Anthropic and OpenAI.
Tenstorrent raises $1.5B at $6.2B valuation: AI chip startup Tenstorrent raised $1.5B, more than doubling its valuation to $6.2B to scale inference chips.
🏆1
Your AI agent can't type into most apps. It only clicks.
CLI-Anything turns GUI-only software like Blender and Obsidian into command lines, so an agent can issue real commands instead of guessing where to click on a screenshot.
▶️ Watch the video on YouTube
7-phase pipeline: analyze, design, implement, test, document, publish
Skill file included: Claude Code, Cursor and OpenCode can discover and drive it
18+ apps wired up: GIMP, Blender, Obsidian, OBS Studio and more
One-command install: pull any generated CLI from the CLI-Hub registry
The real fight: command coverage decides the winner, not CLI versus clicking
https://github.com/HKUDS/CLI-Anything
CLI-Anything turns GUI-only software like Blender and Obsidian into command lines, so an agent can issue real commands instead of guessing where to click on a screenshot.
▶️ Watch the video on YouTube
7-phase pipeline: analyze, design, implement, test, document, publish
Skill file included: Claude Code, Cursor and OpenCode can discover and drive it
18+ apps wired up: GIMP, Blender, Obsidian, OBS Studio and more
One-command install: pull any generated CLI from the CLI-Hub registry
The real fight: command coverage decides the winner, not CLI versus clicking
How CLI-Anything works
It reads an app's source or capabilities and runs them through seven phases: Analyze, Design, Implement, Plan Tests, Write Tests, Document, Publish. The output is a Click-based CLI plus a SKILL.md file, so agents like Claude Code, Cursor, OpenCode or Copilot CLI can find and drive it.
Already-adapted software spans GIMP, Blender, Inkscape, Krita, Audacity, LibreOffice, Draw.io, Obsidian, OBS Studio, Kdenlive, CloudCompare, Godot and more, 18+ harnesses by the latest release line.
CLI-Hub (clianything.cc) is the companion registry. Install any generated CLI withpip install cli-anything-hubornpx skills add HKUDS/CLI-Anything.
The headline number comes from a third-party benchmark (remio.ai), not the project itself: across 440 tasks in 18 apps, the best augmented CLI agent hit 69.3% success versus 59.1% for the best GUI-clicking agent. What it leaves out: the same benchmark's plain, out-of-the-box CLI agent lost to GUI clicking, 48.2% to 59.1%. The CLI only wins once someone manually expands its command set, so the real edge is coverage, not format.
Requires: an adapter generated per app through the pipeline, plus an AI agent harness (Claude Code, Cursor, OpenCode, Copilot CLI) to issue the commands. CLI-Anything itself is free and Apache 2.0 licensed; running an agent against it still means paying for that agent's API key, or self-hosting a model, so this doesn't remove that cost.
Use it instead of a GUI-clicking agent once an app's actions map cleanly to commands you're willing to expand. Don't bother if you need a result today on an app nobody has adapted yet, since the whole gain depends on that upfront work.
https://github.com/HKUDS/CLI-Anything
🔥1
👏1
Argon vs DeepSeek V4.1 Flash vs Muse Spark Open: Who Actually Wins the AI Model War?
Three launches, three strategies: benchmarks, price per million tokens and who holds the weights.
Watch the video on YouTube
Read the article
Three launches, three strategies: benchmarks, price per million tokens and who holds the weights.
Watch the video on YouTube
Read the article
💯1
⚡ AI News
Anthropic, Nscale in talks for second $45B deal: Anthropic and Nscale are negotiating a second $45 billion compute deal, barely two months after the first one.
Microsoft launches Guardian Agents for AI oversight: Microsoft's new Guardian Agents treat frontier AI models as insider threats needing human approval.
Amazon ships TorchNeuron to challenge Nvidia's CUDA: AWS's TorchNeuron runs PyTorch on Trainium chips after a single config change, skipping a code rewrite.
🥰1
CLI-Anything vs Claude Computer Use
Both let an AI agent drive desktop software that has no native API: CLI-Anything scripts a GUI program into typed commands per app, while Claude Computer Use just takes screenshots and clicks like a human. Anyone choosing a GUI-automation strategy for agents weighs these two against each other.
Pick CLI-Anything if your target app is already wired up, or worth scripting yourself, and you want fast, deterministic, auditable commands instead of pixel-clicking
Pick Claude Computer Use if you need an agent to control some app today with zero integration work, run inside an isolated sandbox you do not mind rebuilding
Price
CLI-Anything: free, open source
Claude Computer Use: free tool, pay per token
Setup
CLI-Anything: 7-phase generator per app
Claude Computer Use: sandboxed VM, no adapter
What it does best
CLI-Anything: deterministic commands, 18+ apps
Claude Computer Use: any GUI app, instantly
Main limits
CLI-Anything: only as good as skills
Claude Computer Use: needs sandbox, costs tokens
Who is behind it
CLI-Anything: HKUDS academic lab
Claude Computer Use: Anthropic, commercial lab
CLI-Anything: https://github.com/HKUDS/CLI-Anything
Claude Computer Use: https://platform.claude.com/docs/en/docs/agents-and-tools/computer-use
Both let an AI agent drive desktop software that has no native API: CLI-Anything scripts a GUI program into typed commands per app, while Claude Computer Use just takes screenshots and clicks like a human. Anyone choosing a GUI-automation strategy for agents weighs these two against each other.
Pick CLI-Anything if your target app is already wired up, or worth scripting yourself, and you want fast, deterministic, auditable commands instead of pixel-clicking
Pick Claude Computer Use if you need an agent to control some app today with zero integration work, run inside an isolated sandbox you do not mind rebuilding
Price
CLI-Anything: free, open source
Claude Computer Use: free tool, pay per token
Setup
CLI-Anything: 7-phase generator per app
Claude Computer Use: sandboxed VM, no adapter
What it does best
CLI-Anything: deterministic commands, 18+ apps
Claude Computer Use: any GUI app, instantly
Main limits
CLI-Anything: only as good as skills
Claude Computer Use: needs sandbox, costs tokens
Who is behind it
CLI-Anything: HKUDS academic lab
Claude Computer Use: Anthropic, commercial lab
Side by side, in full
Price
CLI-Anything is Apache-2.0 licensed and free to clone, run, and install generated CLIs from; CLI-Hub charges nothing beyond the ordinary API cost of whatever coding agent runs its short generated commands.
Claude Computer Use: Computer Use carries no separate fee but bills under standard Claude token pricing, and Anthropic's own docs put a single screenshot alone at roughly 1,000 to 1,800 input tokens, so a long clicking session adds up fast.
Setup
CLI-Anything: Setting up CLI-Anything means running its Analyze, Design, Implement, Test, Document pipeline against an app once to generate a Click-based CLI and SKILL.md, or simply running pip install cli-anything-hub and cli-hub install for one of the apps already done.
Claude Computer Use: Setting up Computer Use means standing up a sandboxed Linux container with an X11 virtual display, a window manager, pre-installed apps and an agent loop, for which Anthropic ships a reference Docker image, but no per-app adapter is ever written.
What it does best
CLI-Anything shines on the apps it already covers, among them GIMP, Blender, Obsidian and OBS, turning multi-step GUI workflows into named commands with explicit arguments an agent can inspect before running.
Claude Computer Use: Computer Use works on any application with a screen right now with no integration step, which is why it still beat CLI-Anything's out-of-the-box command set 59.1 percent to 48.2 percent on a 440-task, 18-app benchmark before that set was expanded.
Main limits
CLI-Anything's edge is not automatic: in the same benchmark its plain generated CLI lost to GUI clicking, and only pulled ahead, 69.3 percent to 59.1 percent, after someone manually expanded the command skill set, so an app nobody has adapted yet gets you nothing.
Claude Computer Use: Anthropic's own docs warn Computer Use is vulnerable to prompt injection from on-screen content, struggles with dropdowns and scrollbars, and should only run in an isolated VM kept away from credentials, logins and personal data.
Who is behind it
CLI-Anything is built and maintained by HKUDS, an academic open-source research group, released under Apache-2.0 with community contributions and no vendor support contract behind it.
Claude Computer Use: Computer Use is a commercial Anthropic product, generally available on Anthropic's own API and Google Vertex AI, with beta support on AWS Bedrock and Microsoft Foundry.
CLI-Anything: https://github.com/HKUDS/CLI-Anything
Claude Computer Use: https://platform.claude.com/docs/en/docs/agents-and-tools/computer-use
👍2😁1
DeepSeek just open-sourced its own production inference engine
You could already download DeepSeek's model weights.
Now you can download the exact engine that serves them in production too.
▶️ Watch the video on YouTube
Production engine, not a demo: same optimized kernels and parallelism as DeepSeek's live service
Deterministic sampling: identical output for identical input and seed, NVIDIA only
Structured outputs: locks generation to a JSON schema, regex, or grammar
One model so far: ships only with DeepSeek V4.1 Flash, but the code is Apache 2.0
NVIDIA or Ascend only: needs SM100 GPUs or Ascend 950 NPUs to run at all
deepseek-ai/DeepInfer
You could already download DeepSeek's model weights.
Now you can download the exact engine that serves them in production too.
▶️ Watch the video on YouTube
Production engine, not a demo: same optimized kernels and parallelism as DeepSeek's live service
Deterministic sampling: identical output for identical input and seed, NVIDIA only
Structured outputs: locks generation to a JSON schema, regex, or grammar
One model so far: ships only with DeepSeek V4.1 Flash, but the code is Apache 2.0
NVIDIA or Ascend only: needs SM100 GPUs or Ascend 950 NPUs to run at all
What's inside
DeepInfer is the offline-inference engine DeepSeek runs in production, released as-is rather than a trimmed-down clone. It bundles the optimized kernels (FlashMLA, DeepGEMM, DeepEP, TileKernels, DeepSelect, plus custom TileLang ops), attention/context parallelism, MoE expert parallelism with load balancing, draft-token decoding with confidence-scheduled verification, and a bounded-replay prefill mode that trims redundant work.
Deterministic sampling needsDEEPINFER_BATCH_INVARIANT=1plus a fixedseq_seedpassed toSamplingParams, NVIDIA only. Structured outputs take a regex, JSON schema, or EBNF grammar viaso_args.
The prefill and decode throughput numbers in the README are DeepSeek's own benchmark: measured on 4 SM100 GPUs for prefill and 64 for decode.
Requires: Linux, GCC 13+, Python 3.12, and either CUDA 13 on NVIDIA SM100 GPUs or CANN 9.2 on Ascend 950 NPUs. The project names no fallback for other chips.
It's free and self-hosted, no API key needed, you provide the hardware. The real cost is owning SM100 or Ascend silicon, which most readers won't have lying around.
The catch: this release is offline inference only. No KV cache system, no prefill/decode disaggregation, no load balancing across replicas, so it is not yet a complete serving stack by itself, and only one model is supported.
Use it instead of vLLM when you specifically want DeepSeek's own production kernels for V4.1 Flash. Don't use it if you lack SM100/Ascend hardware or need a ready-made full serving stack.
Code is Apache 2.0. To try it:export DEEPINFER_ACCELERATOR=nvidia
./build.sh
python examples/offline_inference.py
deepseek-ai/DeepInfer
🏆1
Find a file by what's inside it, not what you called it
DigUp searches your photos, PDFs, documents, recordings, videos and code by what's in them.
It runs on your own Mac, Windows or Linux machine, nothing uploaded.
▶️ Watch the video on YouTube
Built on EmbeddingGemma 2: Google DeepMind's model puts text, images, audio and video in one space
Finds the exact moment: type zebra, and it opens the video right where the zebra shows up
Finds the exact page: type the clause about pets, and it jumps to that line in the lease
Over 100 languages: search in English, find a note written in Bengali or Arabic
Free, but not finished everywhere: Mac is stable, Windows and Linux builds are still beta
github.com/ARahim3/DigUp
DigUp searches your photos, PDFs, documents, recordings, videos and code by what's in them.
It runs on your own Mac, Windows or Linux machine, nothing uploaded.
▶️ Watch the video on YouTube
Built on EmbeddingGemma 2: Google DeepMind's model puts text, images, audio and video in one space
Finds the exact moment: type zebra, and it opens the video right where the zebra shows up
Finds the exact page: type the clause about pets, and it jumps to that line in the lease
Over 100 languages: search in English, find a note written in Bengali or Arabic
Free, but not finished everywhere: Mac is stable, Windows and Linux builds are still beta
How it works, and what it takes
DigUp indexes only the folders you pick, and embeds their contents, pictures, PDFs, documents, audio and video, with Google DeepMind's EmbeddingGemma 2: a 740M-parameter multimodal model released in October 2026 under Apache 2.0, small enough to run on a laptop. Text, images, audio and video land in one shared space, so a description in words can match any of them, in more than 100 languages. Exact strings like invoice numbers and error codes still match as written.
The model downloads once (865 MB), then indexing runs locally. By the README's own numbers: on a processor alone, a picture takes about five seconds on a 2017 Core i5 laptop, faster on a GPU; a few hundred files take minutes on a Mac, a full Downloads folder up to an hour. A new file becomes searchable a few seconds after it lands.
Requires: an Apple Silicon Mac on macOS 14+, or 64-bit Windows 10/11, or Ubuntu 22.04/Debian 12/Mint 21+ (or newer) on Intel/AMD. No account, no API key: nothing indexed leaves the machine, it only goes online to fetch the model once and check for updates daily.
The catch: Windows and Linux builds are still beta, and the Windows installer isn't signed yet, so Windows will warn you first; choose More info, then Run anyway.
Try it:brew install --cask arahim3/tap/digupon Mac, the setup.exe from the beta Release on Windows, or on Debian-based Linux:sudo apt install ./DigUp_x.y.z_amd64.deb
(the package is named dig-up). Then press Shift-Cmd-Space or Ctrl-Shift-Space anywhere and describe what you're looking for.
Use it instead of Spotlight or Windows Search when you remember what a file says, not what you called it. Don't reach for it yet if you need Windows or Linux for daily, production use: both are still beta.
github.com/ARahim3/DigUp
🔥1
⚡ AI News
Eric Schmidt holds half Dario Amodei's Anthropic stake: Bloomberg reports Schmidt owns about 1% of Anthropic to Amodei's 2%, worth up to $20B at a $2T valuation.
Google ships TorchTPU to challenge Nvidia's PyTorch grip: Google's open-source PyTorch port for TPUs lets developers move apps off Nvidia GPUs without rewriting code.
US orders federal agencies to purge DeepSeek AI: DHS directs civilian agencies to stop buying and remove DeepSeek software, citing risk of data reaching Chinese authorities.
👏1
This agent gets smarter while its model stays frozen
Google Research built a loop that rewrites an agent's prompt, memory and tools on its own, tests the rewrite, and keeps whichever version wins.
▶️ Watch the video on YouTube
Smarter agent, frozen model: only the harness changes, not the weights
Propose, probe, compose: two tweaks tested per task, the winner kept and reused
Legal benchmark jump: authors report +11.8 points on a legal-work benchmark
Recursion costs compute: up to 20 executor rollouts per task
Guardrails are off by default: network access unrestricted, Codex sandbox disabled
google-research/harness2
Google Research built a loop that rewrites an agent's prompt, memory and tools on its own, tests the rewrite, and keeps whichever version wins.
▶️ Watch the video on YouTube
Smarter agent, frozen model: only the harness changes, not the weights
Propose, probe, compose: two tweaks tested per task, the winner kept and reused
Legal benchmark jump: authors report +11.8 points on a legal-work benchmark
Recursion costs compute: up to 20 executor rollouts per task
Guardrails are off by default: network access unrestricted, Codex sandbox disabled
Harness², explained
Harness² is Google Research's open-source framework (Apache-2.0) for making an agent better at a task without retraining it. It edits the "harness" around a frozen LLM: system prompt, memory, tool guidance, subagents and guardrails. A Propose, Probe, Compose loop drafts two harness tweaks, runs both on the same task, and keeps the one that wins; a persistent "improvement library" carries winning tweaks into later tasks.
The paper (arXiv:2610.14224, Google Research authors) reports gains on three professional benchmarks: up to +11.5 points on WorkBuddy-Bench, +4.5 on JobBench, and +11.8 percentage points of partial pass rate on LAB, a legal-work benchmark, using GLM-5 and Gemini 3.5 Flash as the frozen executor. An independent writeup (Wavect) puts the rollout cost at roughly 4 executor runs per task at the lowest setting, rising to about 20 at the highest, so the benchmark gains come with a multiplying compute bill.
Requires: an existing agent executor to run on top of, OpenCode or Codex, plus API access or local weights for whichever frozen model it harnesses.
The catch: the repo's own README states that in the default setup, executor network access is unrestricted and Codex runs with its sandbox disabled, and it recommends adding network restrictions before any evaluation. The authors themselves document a run where the agent found and used a benchmark's public grading rubric while "improving" itself.
Use it instead of hand-tuning a system prompt once, when you want that tuning to keep improving on its own. Don't use it if you need a result in one pass: recursion here means repeated rollouts, not one quick call.
The framework itself is free and Apache-2.0 licensed. You still pay for whatever model you point it at, locally or through a paid API. It is not an officially supported Google product and is not covered by Google's vulnerability rewards program.
Try it:git clone https://github.com/google-research/harness2
google-research/harness2
❤2🎉1
👍2